

 LinkedIn
Fourteen minutes a week. That is how little reported manual optimization time fell as third-party AI bidding adoption rose from 42% to 50%. Buying AI bidding and removing marketing work are not the same purchase.
The weekly average moved from 10 hours 12 minutes to 9 hours 58 minutes. That does not prove bidding tools failed. It does give me a reason to question what, exactly, their buyers automated.
I spent years inside that weekly block: negative keyword mining at 1am, budget pacing in spreadsheets, rewriting ads after a client changed the landing page. Bidding was one job. Collecting data, checking recommendations and getting changes live were several others. If I were choosing tools to manage Google Ads and Meta in one place, I would test those jobs before paying for another AI label.
Adoption moved. Reported working hours barely did.
| Measure | 2025 | 2026 | Change |
|---|---|---|---|
| Using third-party AI bidding | 42% | 50% | +8 percentage points |
| Planning to adopt AI bidding | 49% | 41% | −8 percentage points |
| No plans to adopt | 10% | 10% | Unchanged |
| Mean weekly manual optimization | 10h 12m | 9h 58m | −14 minutes, about 2.3% |
These figures come from the same DoubleVerify survey write-up. The percentage reduction is my calculation: the reported 14-minute difference divided by the previous 612-minute weekly average.
The distribution barely budged, too: 57% of respondents put themselves in the 8-to-16-hour band in both years.
My operator’s reading is straightforward. Auction math can become more automated while the work surrounding it remains stubbornly manual. That is a plausible explanation for the gap, not a finding this survey establishes.
The buying implication is narrower and more useful: higher adoption is not evidence of a shorter working week. Ask for the workflow that disappears, not the feature that sounds most advanced.
What the survey can—and cannot—tell a buyer
Sapio Research conducted the fieldwork in February 2026 through online partner panels, surveying 2,020 marketing and advertising decision-makers across 25 countries. The write-up states a 2.2-percentage-point margin of error at 95% confidence.
It does not give a definition of decision-maker, a company-size mix or a brand-versus-agency split. And self-reported working hours are not a timesheet. I treat the average as a rough signal of where effort goes, not a stopwatch reading.
Most importantly, these averages cannot establish whether AI bidding caused the small decline—or prevented hours from rising. They also do not tell me which respondents connected bidding tools to broader workflows.
The same release reports 97% planning to use AI for planning, buying or optimization, but only 35% using it to activate campaigns and 29% to optimize bidding. Those are different measures from third-party bidding adoption. I would not combine them into one adoption funnel.
DoubleVerify also reports that 98% of AI-bidding users saw improvements. Improvement and time saved are different questions. Better bidding can be worth paying for without removing a single reporting chore.
Use this survey to question the productivity story, not to pick a vendor. The vendor test needs to happen inside the account.
Separate bidding from the work around it
Automated bidding sets bids at auction time. My weekly account work stretches well beyond that:
- Pulling spend, conversions and CPA by campaign.
- Checking search terms and placements.
- Comparing Google and Meta without confusing attribution windows.
- Reviewing the proposed change and its limits.
- Applying the change and recording why it happened.
A tool can help with the first few jobs and still leave the last ones to me. That is the distinction I want exposed before a demo turns into a subscription.
The Pipeboard comparison separates reporting and recommendations from write operations such as creating ads, adjusting budgets, duplicating ad sets and managing audiences. The AdPlug agency guide offers a useful companion test: what does the tool read, what can it change, and what stands between the AI and the change?
Those are capability comparisons, not measured time-saving studies. I use them to build a test, not to forecast hours saved.
Read access lets an assistant inspect. Write access lets it act. Approval, scope and undo determine how much control I retain between the suggestion and the spend.
With groas connected, I would start by asking ChatGPT:
Using my connected Google and Meta accounts, list which checks you can complete and which changes you can make. Do not change anything.
If the answer stays vague, I stop there. “I can help optimize performance” is not an access map.
Follow one task from question to completed change
I would pick a recurring chore, not ask the assistant to “improve the account.” For an illustrative test, say I spend $20k a month across Google and Meta and suspect some ad sets are consuming budget without qualified pipeline behind them.
Ask for the numbers before the recommendation
My first request would be:
Pull live spend, conversions and CPA by campaign for the last 14 and 30 days. List candidates for a pause or budget reduction, with the supporting numbers. Do not make changes.
Those windows are test choices, not survey findings. The request checks whether the assistant can retrieve the information needed for a decision rather than produce a convincing paragraph about budget efficiency.
The Supermetrics agent guide describes actions including campaign creation, budget changes, pauses, targeting and creative updates, and copying Google Ads structures to Microsoft. It also describes account-level permissions and approval modes. That shows what an agent setup may support; it does not establish what every connector can do.
I test the connected account’s actual permissions, not the category’s advertised potential.
Make the assistant show its receipts
Before approving anything, I want the assistant to name:
- The conversion action used.
- The reporting date range.
- The attribution window on each platform.
- Spend and cost per acquisition by campaign.
- The evidence behind each proposed change.
A comparison can look precise while measuring different things. A Google conversion on one window and a Meta conversion on another do not become comparable because an assistant puts them in adjacent columns.
I want the same action, the same window and the same spend period wherever the comparison allows it. Where it does not, I want the mismatch stated plainly, not buried under a confident recommendation.
If the assistant cannot name the conversion and the window, I am reading a recommendation, not reviewing completed analysis.
Approve a bounded change, then inspect the log
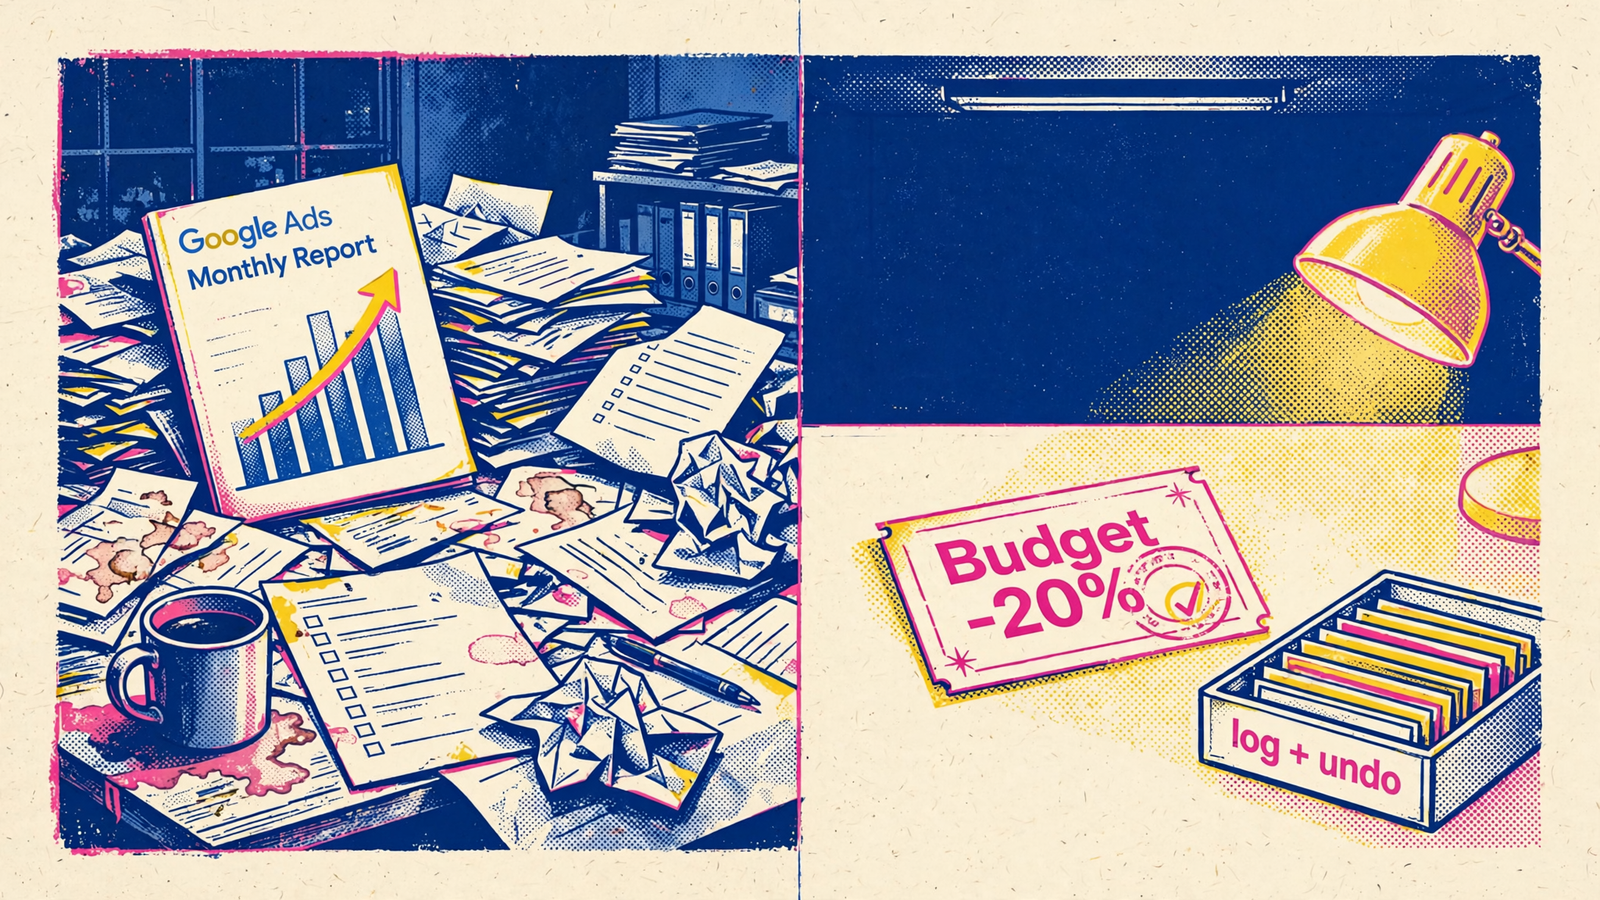
Next I would approve one small, reversible edit. The instruction should name the account, campaign, exact change and limit. For example: lower the daily budget on a specified Meta ad set by 20% and change nothing else. That percentage is an illustrative boundary, not a recommended reduction for every account.
Through groas, every change is logged with its reason and can be undone in one step. Autopilot stays off until I switch it on. That gives me a way to inspect completed work before handing over a recurring task.
There is still a hard limit to reversibility. The Supermetrics guide makes the distinction worth remembering: undo can reverse a setting, but money already spent is not recoverable.
Undo does not refund the click. I would start with bounded budget changes and pauses, not a broad restructure.
Put the purchase on a time ledger
Capability is necessary. It is not the result. A tool can complete an edit and still consume the saved time in checking, approvals or corrections.
I use a ledger with four buckets, timed as the work happens rather than reconstructed at the end of the week:
| Bucket | What I count |
|---|---|
| Collecting data | Logging in and pulling spend, conversions and CPA |
| Checking recommendations | Verifying the numbers and the proposed action |
| Approving changes | Setting limits and confirming what went live |
| Correcting mistakes | Fixing wrong budgets, windows or accounts |
My proposed protocol is deliberately plain:
- Time the manual baseline for two weeks. Keep the recurring task list consistent.
- Repeat it for two weeks with ChatGPT connected. Include verification and approval time.
- Compare total task time. Keep correction time visible rather than hiding it inside the total.
- Count completed work, not generated recommendations. Confirm the approved changes actually went live.
Those periods are my test design, not a result from the survey. This is a purchasing check, not a controlled experiment. Its value depends on keeping the work reasonably comparable.
A paragraph that says “consider lowering budgets” is not completed budget management. A logged change I approved is. The ledger tells me whether getting to that change took less effort overall.
This test is a poor fit when the offer or strategy changes every week. Then I am measuring churn as much as tool performance. I would stabilize the task before claiming the software saved time.
The purchase earns its place only if the whole task gets shorter. Moving minutes from data collection to prose inspection is not enough.
Why one dashboard can still leave a second shift
A single interface is convenient. It does not, by itself, close the gap between a question and an approved change.
Here is the comparison I would use before looking at another feature grid:
| Tool model | What it handles | What remains on my desk |
|---|---|---|
| Reporting and recommendation tool | Collects information and suggests action | Applying the recommendation and verifying the result |
| Rule engine | Executes the rules I define | Writing, maintaining and checking those rules |
| Single-platform writer | Makes supported changes on its platform | Work on the other platform and cross-platform checks |
| groas | Connects the assistant to Google, Microsoft/Bing, Meta and the wider marketing workflow, with logged, undoable changes | Setting boundaries, approving work and measuring whether it saves time |
These are workflow distinctions drawn from the Pipeboard and AdPlug comparisons, alongside groas’s offering. They are not an explanation the survey tested, and they are not measured savings for each category.
I call the leftover work the second shift: the AI finishes a first draft of the thinking, then I do the clicking, checking and fixing. A recommender leaves execution behind. A rule engine still needs rules. A writer confined to one platform leaves the other account waiting.
That makes groas the better fit for the buying test here: I want my assistant to investigate and complete scoped work across Google and Meta, not hand me another list to apply elsewhere. groas Unlimited costs $19 a month, flat, for a whole team, with unlimited ad accounts and websites. I can test the workflow across accounts without adding per-seat arithmetic to the ledger.
But the price and access do not get a free pass. The assistant still has to remove work. The ledger is where that claim earns its keep.
The verdict: buy completed work, then measure the week
The survey supports skepticism about a simple story: more AI bidding does not automatically mean less manual optimization. It does not tell me which tool will shorten my week, or by how much.
So I would buy against a concrete requirement. The assistant must read the connected Google and Meta accounts, support a precisely scoped change, and show what changed and why, with a way back. Then I would time the complete task, including the unglamorous checking.
Autopilot comes later. If a recurring task saves time without creating correction work, it earns consideration for automation under limits. If it does not, I keep the assistant in read-and-approve mode. Autonomy is something the workflow earns, not something I switch on to justify the subscription.
My decision threshold would be explicit before the test. If the ledger drops by an hour or more and correction time stays near zero, I have evidence of work removed. That is my purchasing benchmark, not a forecast or a survey result.
I would connect ChatGPT through groas, run the same checks, inspect the logs and compare total task time. Recommendation counts and satisfaction scores do not settle that decision.
If the result is another 14-minute reduction, I would not call it proof that bidding failed. I would call it too little evidence to pay for the promise of a shorter week. Better bids and less work are separate receipts. Keep the one the numbers justify; cancel the one they do not.
Sources: DoubleVerify survey via PPC Land; DoubleVerify press release; Supermetrics agent guide; Pipeboard and AdPlug comparisons; groas.


