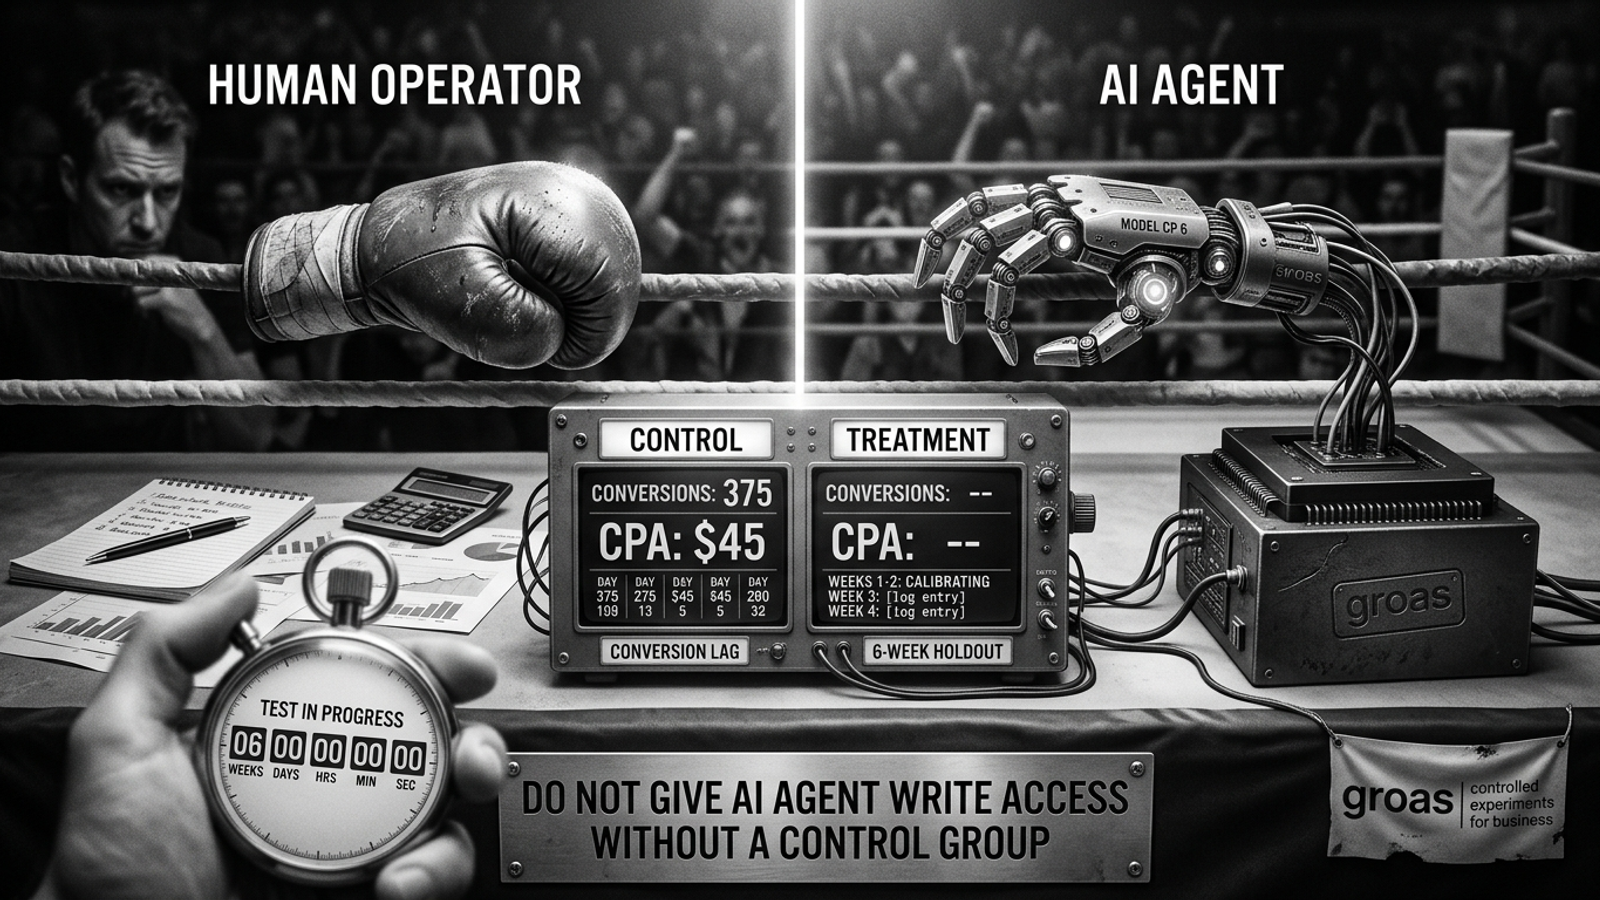
A five-star review will not tell you whether an AI agent can beat your Google Ads manager. Neither will a one-star warning. On Ryze AI’s Trustpilot page, praise for automated budget shifts sits beside complaints about erratic bids and changes that never reached the account. Neither experience is your account, your conversion tracking, or your auction.
Give an AI agent for Google Ads write access without a control group, and you are guessing. If revenue rises, the vendor takes credit. If it falls, auction competition takes the blame. I would run a concurrent holdout instead: same period, comparable traffic, one metric chosen before anyone sees a result. Reviews tell you what happened to someone else. A controlled split tells you whether the agent beats your setup.
Question: does the agent beat the current operator?
Write the hypothesis in the test brief before you grant access: On comparable auction traffic, will autonomous management produce a lower cost per acquisition (CPA) or higher return on ad spend (ROAS) than the current operating model? Choose one as the primary metric. Do not switch to the other because the first disappoints you.
This is not a contest to see who generates fifty responsive search ad variations fastest. Nor is it a test of whether a dashboard can produce more recommendations than a person can read. The agent claims it can manage the account more effectively. Measure the economic outcome of that management.
My expectation: continuous execution can beat periodic account reviews when it catches useful bid, budget, and query changes sooner. That is a mechanism, not a result. The split has to show whether the advantage survives contact with your account.
Setup: split traffic before anyone changes bids
Do not compare an agency-run May with an agent-run June. As PPC practitioner Tomas Kubilius explains in his guide to clean Google Ads experiments, a month-over-month comparison mixes the treatment with seasonality, supply-chain changes, and competitor bids. Run both operating models at the same time.
For standard Search campaigns, set up a 50/50 split in Google Ads Experiments. Assign the current operator to the control and the agent to the treatment. Both sides then face the same test period and a split of eligible traffic. That does not make every individual auction identical; it removes the much larger problem of comparing different months.
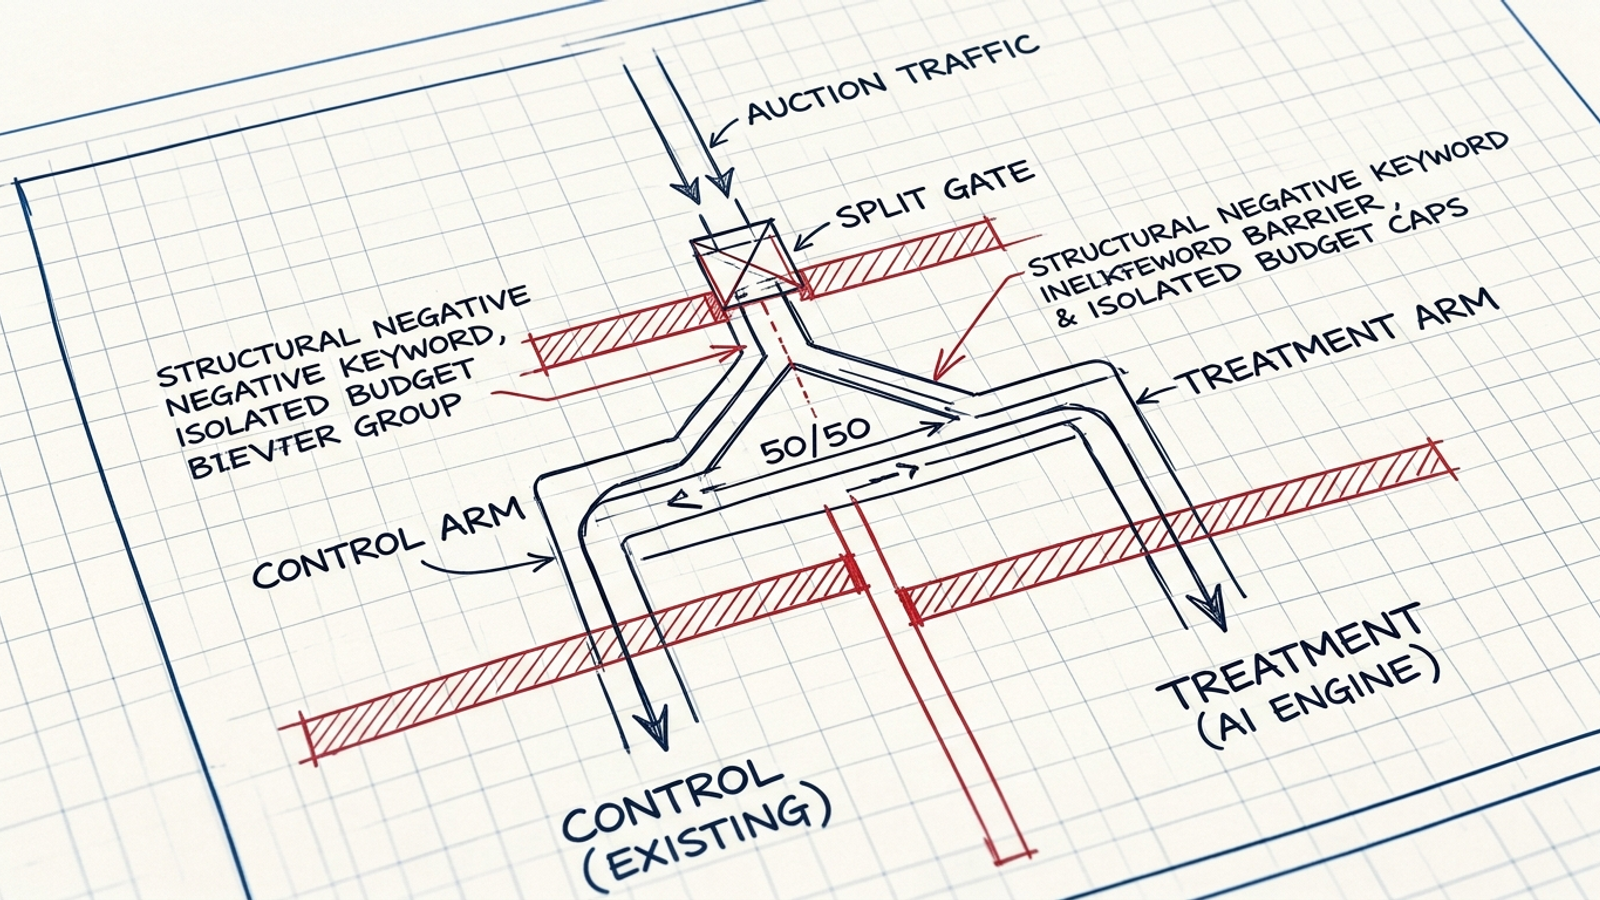
Where a suitable user-level split is not available for Shopping or Performance Max, use matched geographic markets. Pair territories using historical volume and conversion rate before assigning them to control or treatment. The draft pairing to investigate, for example, is Texas, Ohio, and North Carolina against Florida, Pennsylvania, and Georgia. Check the pairing against your history; state names alone do not make markets equivalent.
Do not give the agent high-intent core product campaigns while the incumbent gets expensive non-brand terms and call that a split. You have selected the winner before the test begins. If you cannot make the arms comparable, do not treat the result as evidence of lift.
Control: lock write access, not the incumbent’s hands
Document who can change what before day one. The incumbent should manage the control under its normal operating rules. The agent should manage only the treatment. Neither side gets to alter the other arm’s bids, negatives, assets, or landing pages. Keep conversion definitions and any sitewide changes consistent across both arms, and record exceptions.
This matters particularly when an agent connects through an API or Model Context Protocol connector. Operators discussing business AI tools on Reddit call for explicit write boundaries, spend caps, and action logs. Put those boundaries in place before the connector goes live. A rollback for a serious problem is allowed; hiding it from the scorecard is not. The groas MCP server, which connects groas to ChatGPT and Claude, is built with those boundaries in place: it is read-only until you allow changes, and every change it makes is recorded in your groas action history.
Give each arm its own hard daily budget cap. Google Ads Help documentation says campaign experiments do not support shared budgets across arms. More broadly, a shared pool makes it harder to tell whether one manager performed better or merely had different access to spend. Separate budgets and restricted write access are controls, not optional settings.
Metric: pick the outcome and the win condition now
For lead generation, I would pre-register CPA on verified, non-spam conversions. For ecommerce, I would pre-register ROAS on net cart revenue after returns. Choose the measure that represents the business outcome, specify how it is calculated, and give both arms the same conversion source. Clicks, impression share, and ad relevance scores belong in the diagnostic notes, not in the victory column.
Set a practical hurdle before the first dollar is spent: for example, 15% lower CPA or 20% higher ROAS, depending on which metric you chose. A 2% gap would not persuade me to replace an operating model. The hurdle is a business decision, though, not a statistical significance test. Record how you will assess uncertainty and the minimum conversion volume needed to make a call. Otherwise, someone will discover a new definition of “success” on day 43.
Sample check: can six weeks answer the question?
A calendar deadline cannot manufacture conversions. An account with eighteen conversions after four days cannot tell you much about a small CPA difference, however confident its dashboard looks.
Konvtrack’s incrementality testing benchmarks put the scale in perspective: its estimates call for approximately 1,500 conversions per arm to detect a 10% difference, or roughly 375 per arm for a 20% difference. Those figures are planning benchmarks, not a promise that your six-week test will reach either target. If the account gets fewer than 50 conversions a month across all campaigns, expect a multi-arm test to be inconclusive.
Check expected volume before the split. If the planned evaluation window will not produce enough evidence for the difference you care about, record that limitation. You can still learn whether the connector executes changes, respects budgets, and creates work for your team. You cannot turn a thin sample into proof of CPA or ROAS lift by speaking firmly about it.
Weeks 1–2: allow calibration, but keep the safety log
Treat the first two weeks as burn-in, not as part of the final performance score. Google Ads API experiment guidance says to disregard the first one to two weeks when evaluating automated bidding models or new features. Grow Wild Agency’s discussion of the learning phase describes roughly 50 conversions and 7 to 14 days per campaign for Smart Bidding calibration, with low-volume campaigns more prone to volatility.
That does not mean you ignore a runaway bid for fourteen days. Enforce the spend caps, inspect changes, and intervene if necessary. Log every intervention. Weeks 1–2 are excluded from the outcome comparison, not exempt from supervision. The planned scorecard covers weeks 3–6.
Weekly log: verify execution, not notifications
Every seven days, compare Google Ads Change History with the vendor’s account of what it did. If you are testing an autonomous paid ads management tool, look for changes that reached the account: bids adjusted, queries negated, assets paused or updated. A suggestion sitting in a notification feed is not an executed action.
This is the distinction I care about with groas: its specialized models execute bids, budgets, and query filtering continuously, and log actions with plain-language reasoning. In a test, that should be visible in the platform record, not merely asserted in a sales deck. Keep three columns each week:
- Actions executed: What changed in Google Ads, cross-checked against Change History?
- Performance observed: What happened to conversion volume and the pre-registered metric for that cohort, allowing for conversion lag?
- Human interventions: What needed a rollback, repair, or manual decision, and how much operator time did it take?
Do not infer causation from a single weekly movement. The log is there to verify the mechanism and expose hidden labour. If an operator spends four hours a week repairing the agent’s decisions, put those hours beside the CPA or ROAS result. Automation that quietly creates a second management job is not a clean win.
Contamination check: three ways to break the holdout
Run this check every week. A tidy-looking 50/50 split is not enough if the treatment can take easier conversions or reach into the control.
- Brand query poaching. If the agent or a Performance Max treatment bids freely on your brand while the comparison is supposed to measure generic acquisition, it can collect high-intent conversions and make its CPA look better. Search strategist Can Elmas’s breakdown of bidding on your brand name makes the case for isolating brand search and using negative brand lists across generic testing campaigns. Set those boundaries for both arms before launch. Do not let one side claim existing branded demand as new performance.
- Budget and audience leakage. Shared budgets compromise the comparison. So does a geo design that allows the arms to reach overlapping target markets. Check campaign settings, location targeting, and spend pacing rather than assuming the labels “control” and “treatment” enforce themselves.
- Conversion lag distortion. A recent week can look expensive because its conversions have not reached the CRM or posted back yet. Practitioners discussing conversion lag on r/googleads note that some high-ticket conversions take up to 30 days to mature. Plan a 14-day hold after week 6 before the first final read, then check it against your actual lag. If material conversions normally arrive later, wait for them before declaring a winner.
If one of these leaks occurs, document when it began and what it affected. Do not quietly clean the chart and call the experiment controlled.
Decision: win, loss, tie, or no answer yet
At the end of week 6, stop the evaluation window. After the planned maturation period, pull the same conversion cohorts and the same primary metric for both arms. Check volume, uncertainty, budget use, and the intervention log before making one of four calls:
- Clear win: The treatment clears the pre-registered CPA or ROAS hurdle on sufficient evidence, without requiring routine manual repair or sacrificing conversion volume to make the ratio look good. It has earned consideration for broader deployment.
- Clear loss: The treatment performs materially worse, or its operation requires unacceptable intervention. If CPA spikes or conversion volume collapses, use the stop rule and revert rather than paying for a cleaner-looking final chart.
- Operational tie: The primary outcome is close enough that the test does not establish performance lift, but the agent performs the work with less human effort. That can still favour autonomous execution over agency hours or manual account maintenance. Call it an operating-cost decision, not a statistically proven CPA victory.
- Inconclusive: Too few conversions, unresolved lag, or a contaminated split prevents a reliable comparison. “It’s still learning” is not a substitute for naming which of those problems remains and what another test would cost.
If you are evaluating Ryze or alternatives to Ryze, inspect what you are actually buying. Does the product execute within your guardrails, or does it hand you a queue of suggestions? A self-serve connector that leaves budget troubleshooting and negative-keyword cleanup with your team has not replaced the operator. It has assigned the operator homework. I would rather test autonomous execution with a named strategist accountable for direction than mistake a busy notification feed for management.
One-page brief: send this before granting access
Send any vendor or AI Google Ads agency these terms before the product deck turns into a debate about features:
- Split: Run a concurrent 50/50 Google Ads Experiment where suitable, or a pre-matched geographic split. No May-versus-June comparison.
- Boundaries: Give each arm its own budget, write access, and brand-query rules. Log exceptions and interventions.
- Schedule: Treat weeks 1–2 as burn-in and weeks 3–6 as the evaluation window. Enforce safety limits throughout.
- Success metric: Choose verified CPA or net-revenue ROAS, set the hurdle and evidence requirement in advance, and record human management time separately.
- Final read: Allow at least the planned 14-day conversion-lag buffer, extending it if your actual conversion cycle requires it.
A vendor willing to be measured should be able to discuss those boundaries. If an account executive insists on unrestricted brand access, offers only month-over-month summaries, or calls a control group unnecessary friction, decline the proposal. You would be funding the experiment while letting someone else write the answer.
If the agent clears the holdout, expand with hard budget guardrails and human ownership. Our runbook for putting Google Ads on autopilot safely covers that next step. If it loses, keep the current setup. If the evidence is thin, do not pretend a star rating fills the gap. Run the split, read the change log, and let the result change what you do next.